SQL and Code Studio
Write, debug, and optimize SQL or Python with natural language, with automatic conversion across database dialects.
Covers SQL generation, code explanation, error diagnosis, and script rewriting.
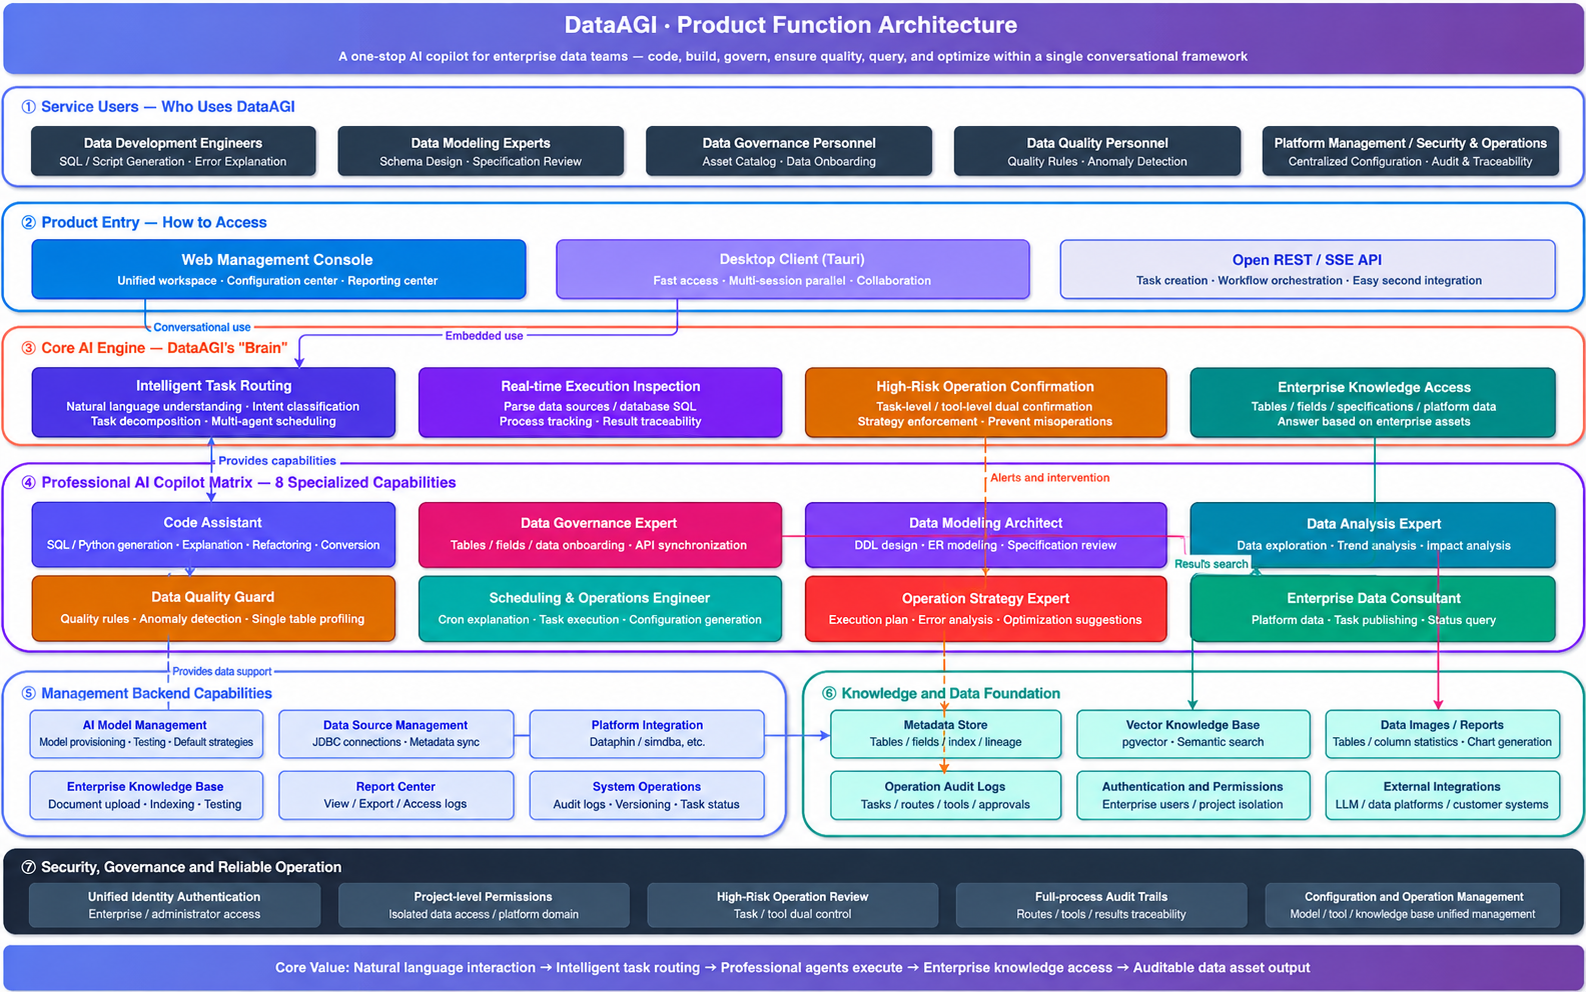
DataAGI is an enterprise AI assistant for data governance and engineering. It turns natural-language requirements into trusted data assets across ingestion, governance, modeling, lineage analysis, and delivery checks, cutting work that once took days down to hours.
Hello! I can help with a range of data tasks, including:
You can ask directly, such as “write a SQL query for customer orders.”
The DataAGI project in Simba contains the following eight tables:
| Table | Chinese Name | Project | Updated |
|---|---|---|---|
| ods_oracle_product__dt | - | DataAGI | - |
| ods_oracle_product_dt | - | DataAGI | - |
| ods_oracle_stock_dt | - | DataAGI | - |
| ods_postgresql_system_area_branch_dt | - | DataAGI | - |
| ods_postgresql_system_branch_office_customer_dt | - | DataAGI | - |
| ods_postgresql_system_branch_office_dt | - | DataAGI | - |
Ask for a table name if you want its field structure and details.
Table ods_oracle_product__dt has the following fields:
| Field | Type | Comment | Primary Key | Partition |
|---|---|---|---|---|
| id | string | - | No | No |
| name | string | - | No | No |
| price | string | - | No | No |
| category | string | - | No | No |
| stock | string | - | No | No |
| create_time | string | - | No | No |
| ds | string | - | No | No |
All fields currently have no comments and are not marked as primary keys or partitions.
Development, modeling, lineage governance, and cost optimization in one workflow
Write, debug, and optimize SQL or Python with natural language, with automatic conversion across database dialects.
Covers SQL generation, code explanation, error diagnosis, and script rewriting.
Automatically interpret requirements, generate standards-compliant DDL, audit DDL conventions, and encode expert practices into standardized algorithmic models.
Keeps data asset modeling faster, cleaner, and more consistent.
Parse field-level lineage, visualize topology, generate quality rules, and accelerate impact analysis and driver analysis.
Helps teams see downstream impact before model and field changes go live.
Identify skewed or costly jobs, explain execution plans, and produce retirement lists and cost forecasts.
Improves task stability and troubleshooting from anomaly detection to resource tuning.
An automated data productivity engine for faster, more reliable, and higher-quality delivery
Move from natural-language requirements to end-to-end development, reducing delivery from days to hours.
Incorporate expert architecture practices and block defined data-security policy violations.
Help data architects improve architecture design, code generation, quality validation, and delivery coordination.
Continuously learn business logic and team habits to form long-term enterprise data memory.
Connect requirements, development, governance, and delivery into an automated workflow

Collaborative delivery for data developers, architects, and business teams