Data Built for AI
Redefine how data is organized, accessed, and protected so enterprise data is ready for foundation model use cases.
Turn enterprise data into a foundational asset for the AI era
Simba Data Foundation is one of two core pillars of the enterprise AGI platform, alongside the model foundation. It connects enterprise-scale data assets with AI capabilities, bringing together data ingestion, governance, knowledge capture, and secure delivery so models and intelligent business applications can access trusted, governed data on demand.
The data foundation goes beyond a traditional data platform. It organizes enterprise data into production-ready assets that AI and other IT systems can reliably consume and reuse.
Redefine how data is organized, accessed, and protected so enterprise data is ready for foundation model use cases.
Support full-stack private deployment so enterprise data remains within your environment, helping protect data sovereignty and support compliance.
Turn metrics, business rules, industry practices, and expert knowledge into structured assets AI can reuse.
Unify integration, governance, and delivery to reduce duplicate work and accelerate the journey from AI pilots to scaled deployment.
Keep high-value data ready to support models and business decisions.
Deliver stable, model-facing throughput for EB- and PB-scale data flows.
Low-latency, high-throughput data APIs through a unified interface, supporting 100K+ QPS.
Unified stream and batch processing, delivering query results within seconds—even for complex queries spanning large datasets, multiple sources, joins, and business rules.
High-efficiency encoding reduces storage requirements to one-third to one-fifth of their original size.
Bring together enterprise data sources, governance systems, knowledge assets, and access controls to provide AI applications with governed, trusted, on-demand data context.
Unify databases, warehouses, data lakes, APIs, files, and streaming data.
Identify schemas, field semantics, and relationships while managing catalogs, lineage, and lifecycle.
Transform metric definitions, industry rules, business logic, and expert knowledge into structured, reusable AI assets.
Bring together row- and column-level permissions, on-demand context loading, audit trails, and private deployment controls.
Traditional data platforms serve people. This data foundation serves models. It helps models understand business terms, honor access controls, access trusted data, and continuously turn enterprise knowledge into reusable intelligence assets.
Simba brings together schemas, metadata, metrics, semantic layers, access policies, and caching to create a model-ready data service layer, so downstream applications receive stable, accurate, and auditable data context.
Connect relational databases, data warehouses, data lakes, APIs, files, and streaming data using low-code connectors.
Ingest schemas, manage metadata and lineage, and capture metrics, semantic layers, industry rules, and expert practices.
Use row- and column-level permissions, on-demand context loading, and audit trails so models only see authorized, business-aligned data.
General-purpose models are widely available, but AI that understands your business, uses your data, and respects your boundaries must be built on your own enterprise data foundation. Simba turns data assets into a continuously evolving enterprise intelligence layer.
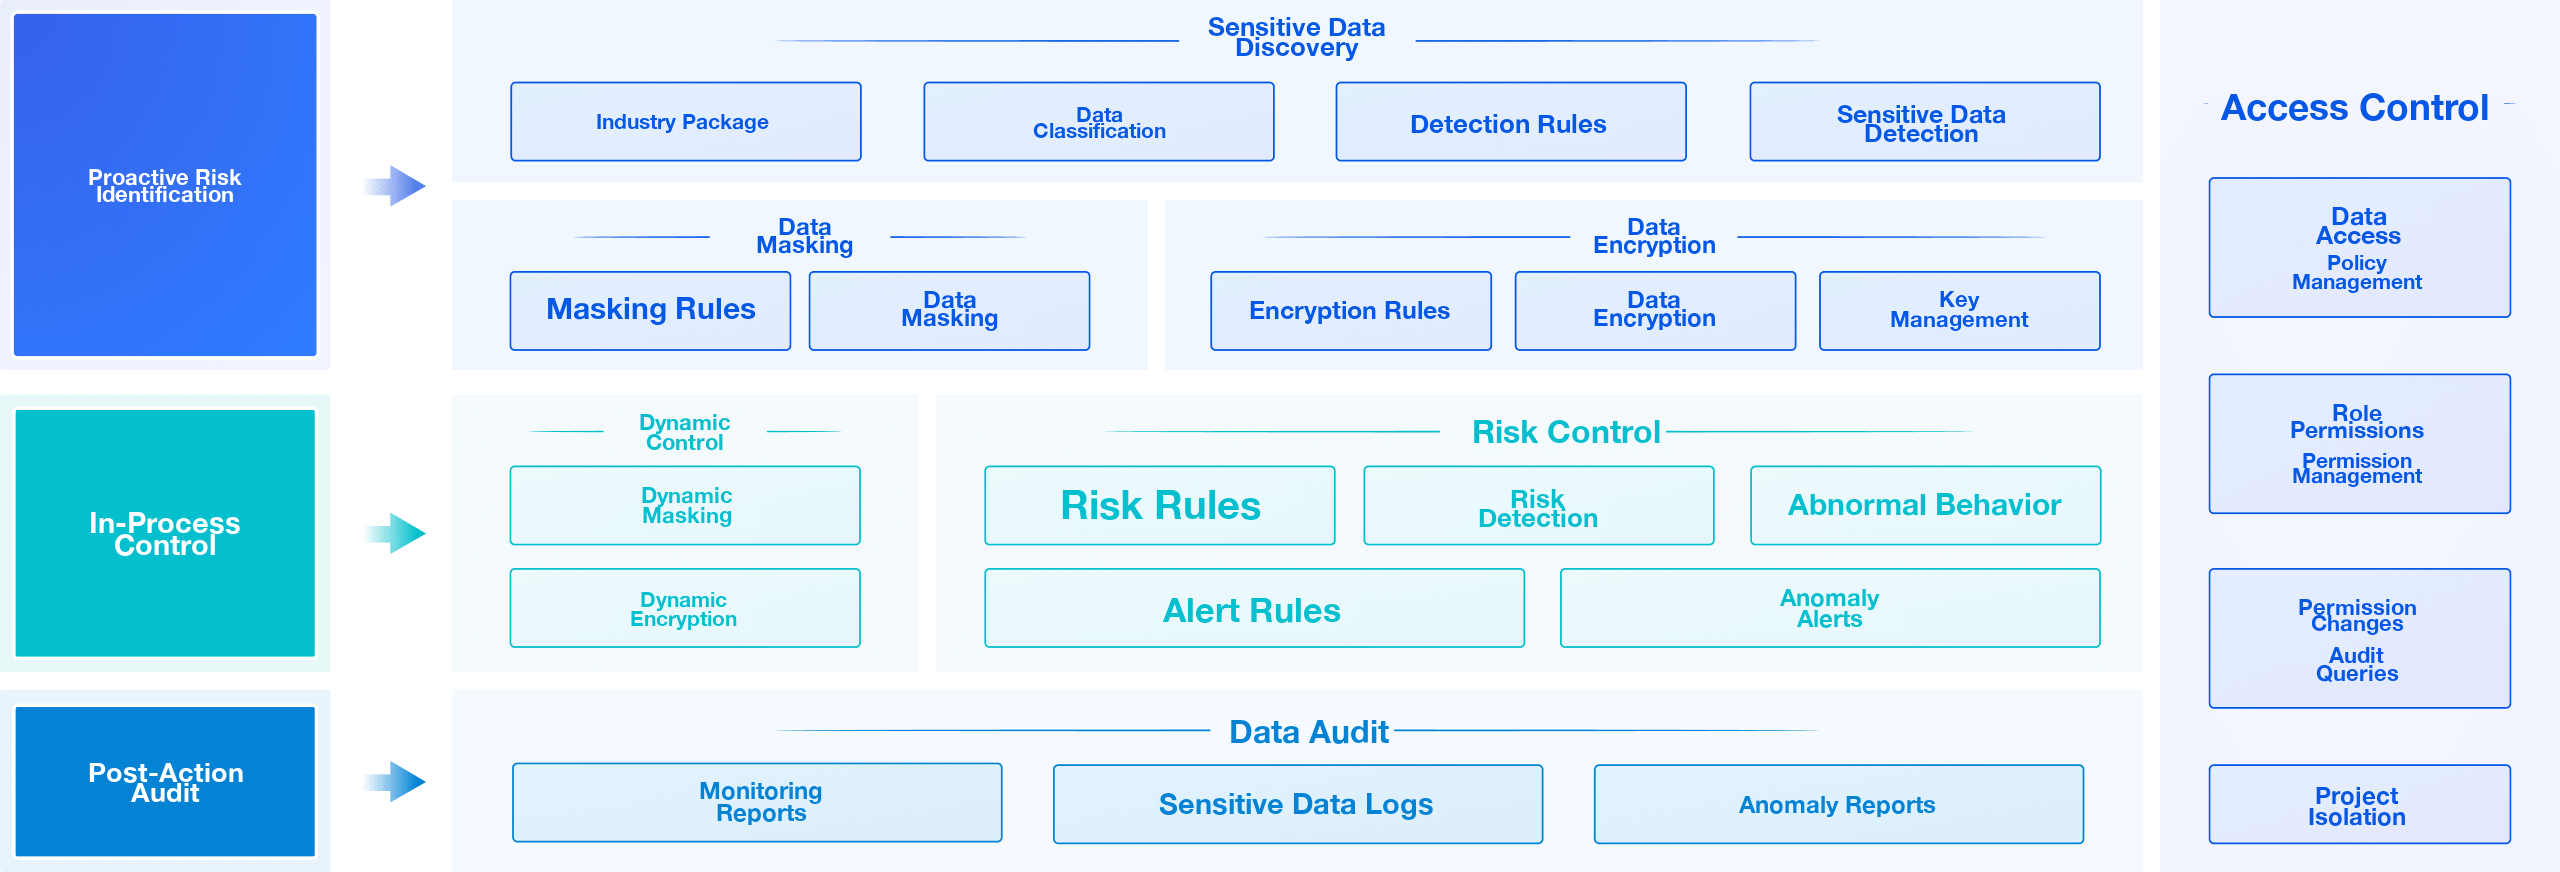
DataBlack is StartDT's data security engine. Built on a data-centric security architecture, it helps enterprises protect data across the full lifecycle, strengthen governance and risk management, and safeguard data assets.
More comprehensive. More intelligent.
Apply comprehensive security controls across data flows and sensitive data.
Apply intelligent algorithms and trained models to identify sensitive data faster and more accurately.
Provide detailed audit records, including sensitive-data usage, to support security and compliance requirements.
Support static and dynamic masking, encryption, and authorized decryption to protect sensitive data in use, at rest, and in transit.
Monitor high-risk user actions with custom rules or intelligent algorithms, and trace activity through security audit logs.
Security Throughout the Data Lifecycle
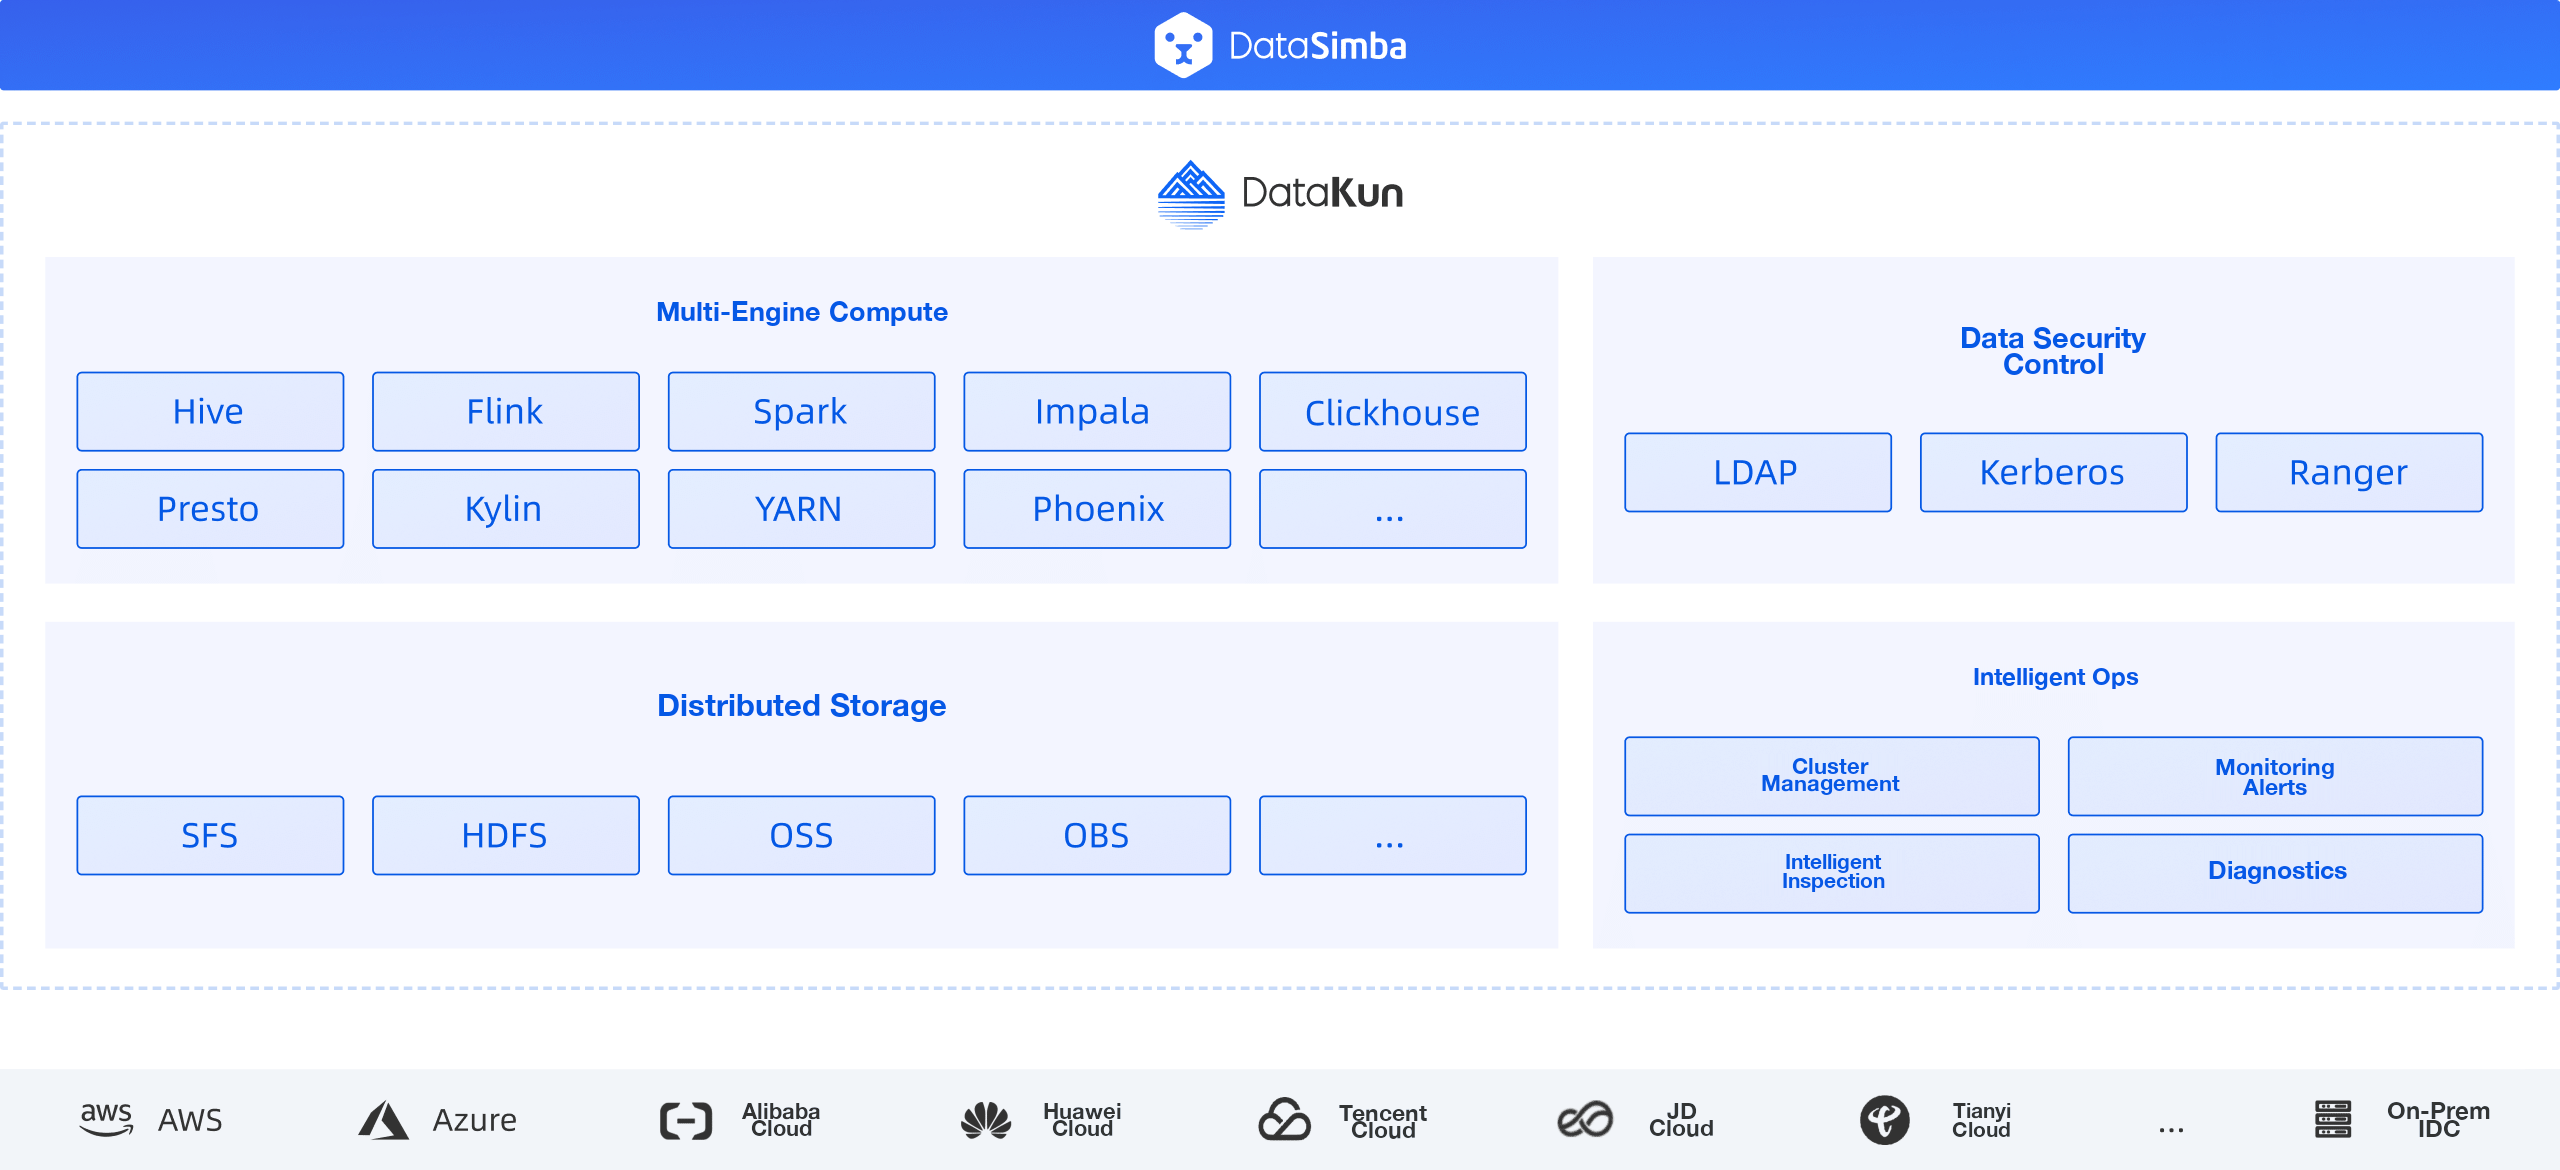
DataKun is an independently managed storage and compute engine that helps enterprises build a lightweight, intelligent data platform and develop their own analytics and processing capabilities. It supports multiple big-data jobs and services, custom components, validated version combinations, and continuous upgrades of core components.
Technology You Control. Cost Efficiency.
Open, manageable, extensible, and continuously evolving